High-Performance Edge Tunneling Architecture: Kernel Bypass, XDP, and BBR Tuning
Discover how to accelerate tunnel throughput using Solarflare Onload, DPDK, XDP packet filtering, and TCP BBRv3 tuning for high-performance edge networking.
Quick answer
Low-Level Networking & Kernel-Level Optimization for Edge: localhost tunnel answer
A localhost tunnel gives your local app a public HTTPS URL without opening router ports, which is useful for demos, QA, mobile testing, and provider callbacks.
How do I expose localhost without opening ports?
Use a reverse HTTPS tunnel. Your machine connects outbound to the tunnel service, and the public URL forwards requests back to your local app.
When should I use a localhost tunnel?
Use one for webhook testing, OAuth callbacks, client demos, QA previews, mobile device checks, and short-lived development reviews.
In latency-sensitive systems such as trading gateways, telemetry pipelines and edge relay meshes, the general-purpose Linux network stack can become the bottleneck. Per-packet work in the kernel adds jitter, and oversized queues on the path add delay. A tunnel relay that forwards millions of packets per second feels both problems.
This guide covers three techniques that attack different parts of the problem:
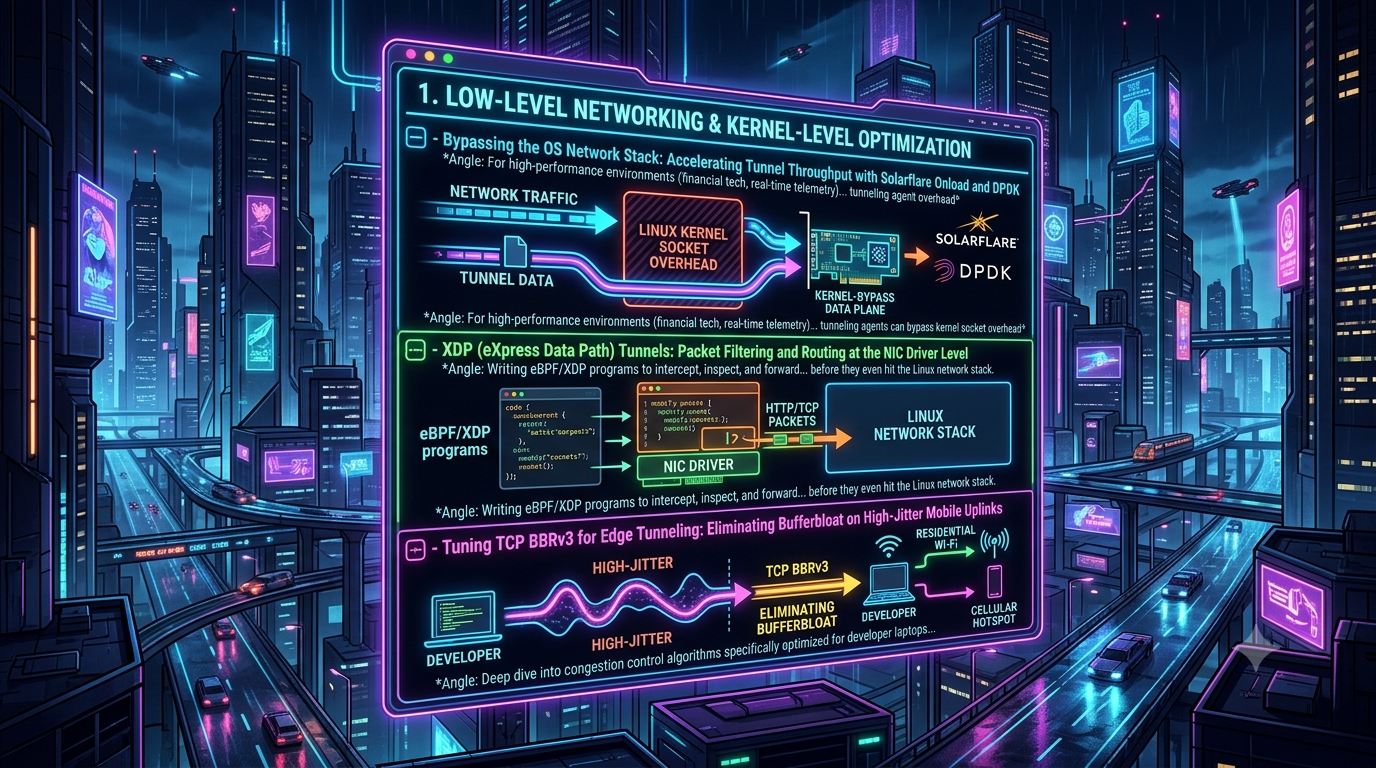
- Kernel-bypass data planes with AMD Solarflare Onload and the Data Plane Development Kit (DPDK).
- eBPF/XDP (eXpress Data Path) for filtering and redirecting packets at the driver level, before the kernel allocates socket buffers.
- BBR congestion control for paths with variable bandwidth and deep buffers, such as cellular and residential Wi-Fi uplinks.
One caveat applies throughout. Only kernel bypass and XDP help with per-packet CPU cost. BBR addresses queueing delay on the network path, which is a different problem. Pick the technique that matches the bottleneck you have measured.
1. Kernel Bypass: Onload and DPDK
Where the standard stack spends its time
On the normal Linux receive path, the NIC raises an interrupt and the kernel’s NAPI layer polls the device. The driver then allocates an sk_buff, and the packet passes through the protocol layers and netfilter hooks. Finally, a system call such as recv copies the payload into user memory.
Modern kernels batch much of this work with NAPI and interrupt coalescing, so it is not one interrupt per packet. Even so, at very high packet rates the allocation, copying, locking and cache traffic add up and make latency less predictable.
Kernel-bypass designs move the data path into user space. The NIC delivers packets by DMA into memory the application owns, and the application processes them without per-packet system calls.
Onload: transparent acceleration for socket applications
Solarflare was acquired by Xilinx and is now part of AMD. Its Onload software is still developed under the AMD Solarflare name, with source available as OpenOnload on GitHub.
- How it works: OpenOnload is a user-level shared library that intercepts network-related system calls and implements the TCP/UDP protocol stack in user space. It is supported by kernel modules and is binary compatible with existing BSD-sockets applications. Most applications therefore need no code changes.
- Hardware path: Onload uses the native
ef_viinterface on AMD Solarflare adapters.ef_viis a low-level, ultra-low-latency API that applications can also call directly. - Other NICs: Onload can also run over Linux’s AF_XDP mechanism, which does not need Solarflare hardware. The project’s documentation notes that the native
ef_vipath gives better acceleration and extra features than AF_XDP mode. - Current hardware: AMD’s current line is the Alveo X3 series, with up to 4×10/25 GbE ports. It supports full kernel bypass through Onload, TCPDirect and
ef_vi. TCPDirect is a separate user-space stack that AMD describes as reaching even lower latency than Onload. Older SFN8522 and SFN8542 adapters remain on Onload’s supported-hardware list. - Kernel support: The upstream repository tracks recent kernels, and its README currently lists kernel.org kernels from 6.1 to 7.0. Check it before pinning a kernel version.
DPDK: a polling framework you build around
DPDK is a user-space framework built around poll-mode drivers (PMDs). Your application polls NIC receive queues in a busy loop, so there are no interrupts on the data path. Packet buffers come from hugepage-backed memory pools. Unlike Onload, DPDK is not transparent: you write your own packet-processing loop, and the NIC is taken away from the kernel network stack for the duration.
For release planning, 25.11 is the current upstream LTS. DPDK follows a roughly four-month cadence, and the project’s published schedule lists 26.11.0 for 18 November 2026.
Production checklist for bypass deployments
- Isolate cores. Dedicate cores to polling threads and keep other work off them. DPDK’s performance guide suggests
isolcpustogether with hugepage reservation on the kernel command line. Since Linux 6.6 the default scheduler is EEVDF, which replaced CFS. Core isolation matters under either scheduler, because a polling thread should never share a core with unrelated work. - Keep everything NUMA-local. DPDK’s guide says to put the polling cores and the NIC on the same socket for best performance. You can find a NIC’s node in
/sys/bus/pci/devices/<address>/numa_node. Allocate packet buffers from that same node. - Reserve hugepages at boot for packet memory pools.
- Plan for operations. A bypassed interface no longer shows up in
tcpdump, iptables or the usual kernel observability tools in the normal way. Plan your monitoring and debugging before you go live.
Vendors publish latency comparisons for these stacks, such as AMD’s own Onload versus kernel TCP results. Treat them as vendor measurements taken on specific hardware, payload sizes and tuning, and benchmark your own workload.
2. XDP: Programmable Packet Handling at the Driver
XDP was introduced in Linux 4.8 and is built on eBPF. With native driver support, an XDP program runs right after the NIC receives a packet and before the kernel allocates a socket buffer. This is what makes drops and redirects so cheap. Unlike a full bypass, XDP works alongside the normal kernel stack, so ordinary sockets, tooling and the rest of your system keep working.
Execution modes
- Native (driver) mode: the default and the fast path. It requires driver support.
- Generic (SKB) mode: works on any interface by running the hook after the stack has allocated an
sk_buff. It is useful for development, but it loses most of the performance benefit. - Hardware offload: the program runs on the NIC itself. Support is rare. According to the xdp-tools documentation, Netronome/Corigine cards using the
nfpdriver are the only devices supporting it in the mainline kernel.
Example: an allowlist for tunnel peers
This sketch drops UDP traffic to the tunnel port unless the source address is in an allowlist map maintained from user space. Linux’s VXLAN driver defaults to UDP port 8472. The IANA-assigned VXLAN port is 4789, and Linux kept 8472 for historical reasons. VXLAN runs over UDP, not TCP. The same logic applies to any UDP-based tunnel.
This is an illustrative sketch, not a hardened firewall. Build and load it with libbpf and xdp-tools.
#include <linux/bpf.h>
#include <linux/if_ether.h>
#include <linux/in.h>
#include <linux/ip.h>
#include <linux/udp.h>
#include <bpf/bpf_helpers.h>
#include <bpf/bpf_endian.h>

#define TUNNEL_PORT 8472

struct {
    __uint(type, BPF_MAP_TYPE_HASH);
    __uint(max_entries, 1024);
    __type(key, __u32);   /* IPv4 source address */
    __type(value, __u8);
} allowed_peers SEC(".maps");

SEC("xdp")
int tunnel_peer_filter(struct xdp_md *ctx)
{
    void *data     = (void *)(long)ctx->data;
    void *data_end = (void *)(long)ctx->data_end;

    struct ethhdr *eth = data;
    if ((void *)(eth + 1) > data_end)
        return XDP_PASS;
    if (eth->h_proto != bpf_htons(ETH_P_IP))
        return XDP_PASS;

    struct iphdr *iph = (void *)(eth + 1);
    if ((void *)(iph + 1) > data_end)
        return XDP_PASS;
    if (iph->protocol != IPPROTO_UDP || iph->ihl < 5)
        return XDP_PASS;

    struct udphdr *udph = (void *)iph + (iph->ihl * 4);
    if ((void *)(udph + 1) > data_end)
        return XDP_PASS;

    if (bpf_ntohs(udph->dest) != TUNNEL_PORT)
        return XDP_PASS;

    __u32 src = iph->saddr;
    if (!bpf_map_lookup_elem(&allowed_peers, &src))
        return XDP_DROP;   /* unknown peer: drop before the stack sees it */

    return XDP_PASS;
}

char _license[] SEC("license") = "GPL";
XDP actions
XDP_DROP: discards the packet at the driver, and the buffer is recycled to the receive ring. This makes it effective against floods and for blocklists.XDP_PASS: hands the packet, possibly modified, to the normal network stack.XDP_TX: sends the packet back out of the interface it arrived on. Load balancers use this after rewriting addresses.XDP_REDIRECT: sends the frame elsewhere, using a redirect map. Common targets are another XDP-enabled interface (devmap), another CPU (cpumap), or a user-space AF_XDP socket (xskmap).
AF_XDP is the bridge to the previous section. It lets user space receive raw frames from a driver queue without traversing the full network stack. An AF_XDP socket binds to a single netdev queue, and the XSKMAP type has existed since Linux 4.18. It gives a DPDK-like user-space data path while keeping the NIC under kernel control. DPDK itself also has an AF_XDP PMD, and Onload can use AF_XDP, as noted above.
3. Congestion Control for Variable-Rate Edge Links
The problem
Mobile hotspots, residential routers and cellular base stations often keep large queues, which causes bufferbloat. A loss-based algorithm such as CUBIC keeps increasing its window until a buffer overflows. The queue sits full, and latency for every flow sharing it goes up.
After a loss event, CUBIC reduces its congestion window by a factor of 0.7 (RFC 9438 sets the multiplicative decrease factor at 0.7, compared with 0.5 for classic Reno). So it cuts the window by about 30%, not 50%.
What BBR does differently
BBR is a model-based algorithm. It estimates two path properties:
- BtlBw: the bottleneck bandwidth, the maximum rate the path can deliver.
- RTprop: the round-trip propagation delay, the baseline delay with empty queues.
It paces packets at the estimated bandwidth and tries to keep the amount of data in flight close to the bandwidth-delay product (BDP), BtlBw × RTprop. That keeps queues short and throughput high without relying on packet loss as the main signal.
BBRv3 is probably not in your kernel
Setting net.ipv4.tcp_congestion_control = bbr on a mainline Linux kernel gives you BBRv1, not v3. The mainline tcp_bbr module has been BBRv1 since it was merged in Linux 4.9. Google’s BBRv3 lives in a separate branch (v3 of the google/bbr repository), which has been rebased onto newer kernels. Maintainers of the BBR code stated in 2025 that net-next and mainline still carried BBR 1.x. A later Google team statement had no new BBR release to announce. I found no evidence of a mainline merge as of this writing.
Because the sysctl value is just bbr either way, you cannot tell v1 from v3 from the setting. Check where your kernel came from, whether Google’s v3 branch, a distribution kernel that carries the patches, or a third-party kernel build. The BBRv3 README documents sysctl net.ipv4.tcp_available_congestion_control for checking available algorithms, plus patched iproute2 tools for BBRv3’s ss output.
BBRv3 is also being standardized. The IETF Congestion Control Working Group’s draft draft-ietf-ccwg-bbr, whose latest revision (-06, July 2026) states that it specifies version 3 of the algorithm, is intended for publication as an Experimental RFC.
Relative to v1, BBRv2 and v3 take loss and ECN signals into account, to improve coexistence with loss-based flows such as CUBIC.
Where it applies in a tunneling stack
Congestion control runs on the sender of the data. For a tunnel relay, that means:
- The setting on the relay governs traffic it sends toward clients, such as downloads through the tunnel.
- A client’s setting governs its own uploads over its local uplink.
Changing only the relay does nothing for the upload direction from a laptop on a cellular link. Also, if your tunnel carries TCP inside TCP, the inner and outer congestion controllers interact, which is a known source of poor behavior. UDP-based tunnels such as WireGuard avoid the outer TCP loop.
Baseline sysctl configuration
Put this in /etc/sysctl.d/99-edge-bbr.conf:
# Fair queuing qdisc: handles pacing efficiently for many flows
net.core.default_qdisc = fq

# Use BBR (v1 on mainline kernels; v3 only on kernels that carry it)
net.ipv4.tcp_congestion_control = bbr

# Raise buffer ceilings for high bandwidth-delay-product paths
net.core.rmem_max = 67108864
net.core.wmem_max = 67108864
net.ipv4.tcp_rmem = 4096 87380 33554432
net.ipv4.tcp_wmem = 4096 65536 33554432
Notes on these settings:
fqis recommended, not strictly required. Since Linux 4.13, the TCP stack has an internal pacing fallback, so BBR works with other qdiscs. The kernel commit notes that withoutsch_fq, TCP paces with one high-resolution timer per socket. Linux network maintainer Eric Dumazet has said that if you run BBR at scale (thousands of machines), you should usesch_fqrather than internal pacing.- Buffer sizes should match your paths. A 32 MiB maximum buffer suits roughly a 1 Gbit/s path at about 250 ms RTT (≈31 MB of BDP). Smaller values are fine for slower or shorter paths. Larger buffers cost memory per connection.
- Window scaling and timestamps are enabled by default on current kernels, so they need no entries.
ECN: optional, and easy to get wrong
ECN lets routers signal congestion by marking packets instead of dropping them. The kernel default for net.ipv4.tcp_ecn is 2, which accepts ECN on incoming connections but does not request it on outgoing ones. Setting it to 1 requests ECN on outgoing connections too.
This only helps if the bottleneck router actually applies ECN marking. Do not assume it is a free win. BBRv3’s own ECN logic is controlled by a per-route ecn_low feature, which the README describes as meant for environments where you know that ECN marks will be DCTCP/L4S-style marks. Those are very different from classic RFC 3168 marking on a consumer router. For a typical tunnel with unknown last-mile networks, leave that feature off. Enable tcp_ecn = 1 only after testing against your real paths.
Verifying behavior
Use ss to inspect live sockets:
ss -tin '( dport = :443 or sport = :443 )'
The output includes pacing_rate, delivery_rate and minrtt. On BBRv1 kernels you also get a bbr:(...) block with bandwidth and RTT estimates. On BBRv3 kernels, the patched ss from the BBRv3 distribution prints v3-specific state. These fields confirm that BBR is active and what it estimates. They do not by themselves prove lower latency. Measure latency under load, for example by running a ping alongside a bulk transfer and comparing results with CUBIC and with BBR.
Choosing the Right Tool
| Problem | Technique | Cost |
|---|---|---|
| Socket-API app is limited by kernel CPU and jitter | Onload (transparent) | Specific NICs or AF_XDP mode, plus the Onload kernel module |
| Highest packet rate on a purpose-built data plane | DPDK | Full application rewrite around a polling loop, dedicated cores and NICs |
| Early filtering or redirection, and you want to keep the kernel stack | XDP / AF_XDP | eBPF development, driver support for native mode |
| High latency under load on variable last-mile links | BBR with fq, tested against CUBIC |
Check which BBR version you actually run |
For most developer-facing tunneling relays, an XDP allowlist and sensible congestion-control tuning are realistic first steps. Full kernel bypass belongs to the narrow set of workloads where the kernel stack has been measured as the bottleneck.
References
- DPDK Linux getting-started guide: NIC performance on Intel platforms
- DPDK release status minutes, August 2026
- Xilinx-CNS/onload on GitHub
- AMD Alveo X3 series adapters
- Kernel documentation: BPF_MAP_TYPE_XSKMAP
- xdp-loader(8) manual page
- google/bbr, v3 branch README
- bbr-dev thread: using BBRv3 with newer kernels
- IETF draft-ietf-ccwg-bbr-06
- RFC 9438: CUBIC
- Linux kernel commit 218af599fa63: internal TCP pacing
- Linux 6.6 EEVDF scheduler (Phoronix)
Related InstaTunnel pages
Continue from this article into the most relevant product guides and workflows.
Related Topics
Keep building with InstaTunnel
Read the docs for implementation details or compare plans before you ship.