Low-Level Networking & Kernel-Level Optimization: Architecting Ultra-High-Throughput Tunnels in Go and Rust
Master low-level networking for local development tunnels. Learn to implement zero-copy system calls, scale with SO\_REUSEPORT, and fix buffer bloat.
Quick answer
Zero-Copy Ingress & Kernel Optimization for High-Throughput: webhook testing answer
For local webhook testing, run your app locally, expose it with a public HTTPS tunnel, and paste the stable callback URL into the provider dashboard.
How do I test webhooks on localhost?
Start your local server, open a public HTTPS tunnel to that port, configure the provider webhook URL, and inspect events in your local logs.
Why does a stable webhook URL matter?
Stable URLs prevent provider dashboards from needing manual callback updates every time you restart a tunnel.
Modern distributed systems, local development tunneling tools (such as ngrok, Cloudflare Tunnels, or custom enterprise ingress gateways), and high-frequency webhook routers face an uncompromising bottleneck: the Linux kernel-user space boundary. When scaling proxy daemons to handle hundreds of thousands of concurrent connections processing gigabits of telemetry, API payloads, or file transfers, traditional socket programming patterns (read() and write()) break down. CPU cycles are wasted on context switches, memory buses saturate from redundant buffer copying, CPU caches thrash, and tail latencies skyrocket.
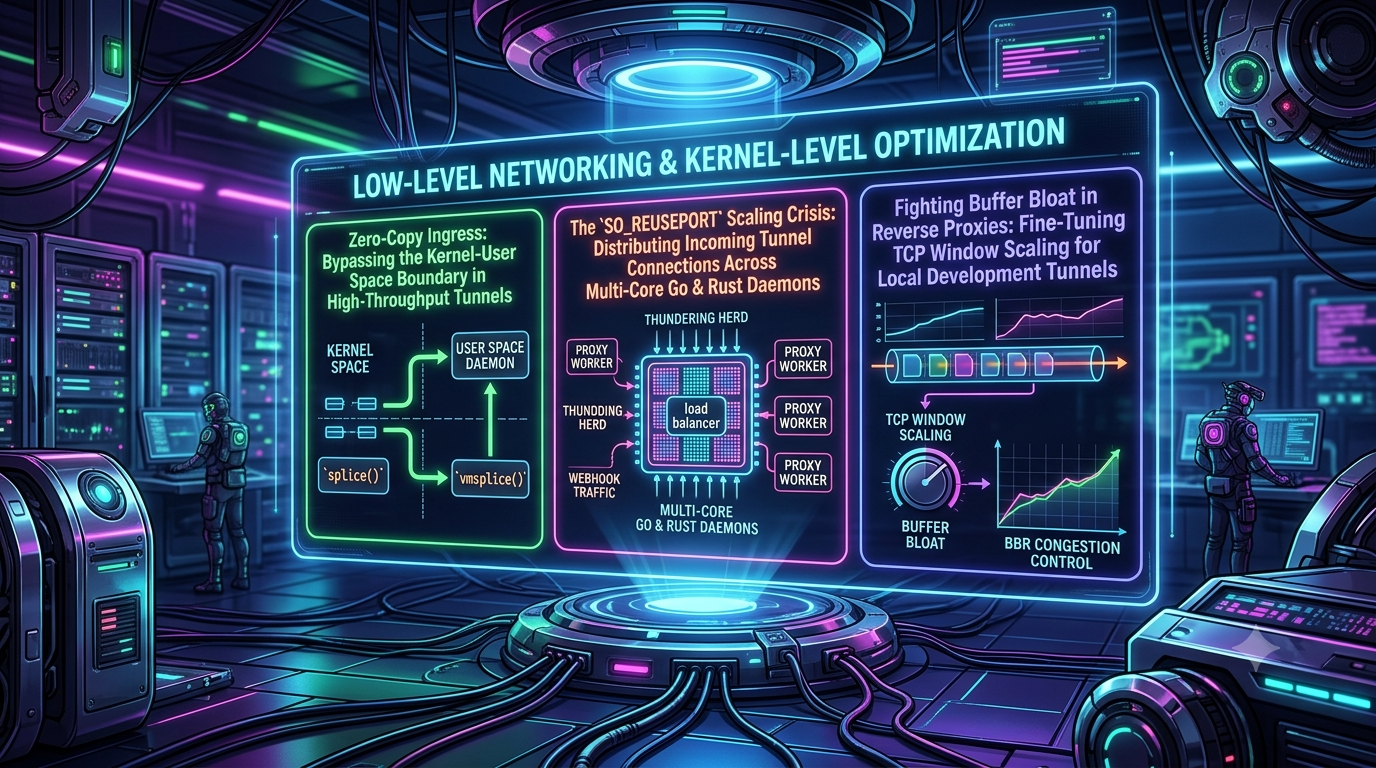
Achieving wire-speed tunneling performance requires diving deep into the Linux networking stack. This comprehensive guide explores three critical pillars of low-level optimization: bypassing the kernel-user space boundary using zero-copy primitives like splice(), resolving the SO_REUSEPORT scaling crisis across multi-core Go and Rust daemons, and eradicating buffer bloat via BBR congestion control and socket tuning.
1. Zero-Copy Ingress: Bypassing the Kernel-User Space Boundary in High-Throughput Tunnels
The Cost of Standard I/O in Proxies
In a standard proxy daemon implementation, moving data from an incoming network socket to an outgoing tunnel connection involves multiple memory copies and context switches. Consider a traditional data path for a proxy payload:
- NIC to Kernel Socket Buffer: Network interface card (NIC) DMA writes incoming packet data into the kernel ring buffer (sk_buff).
- Context Switch 1: The CPU triggers a hardware interrupt, transitioning from kernel space to user space when the application calls
read(). - Copy 1 (Kernel to User): The kernel copies data from the kernel socket read buffer into a user-space buffer allocated by the proxy daemon (e.g., a byte slice in Go or a
Vec<u8>in Rust). - Context Switch 2: The proxy daemon processes or inspects the header, then invokes
write()orsend()to transmit the payload to the backend or tunnel peer, shifting execution back to kernel space. - Copy 2 (User to Kernel): The kernel copies data from the user-space buffer into the destination socket’s write buffer.
- Kernel to NIC: The network driver takes the data from the kernel write buffer and transmits it via DMA to the NIC.
For a proxy handling 10 Gbps of traffic, this architecture forces the CPU to copy every single byte twice and endure millions of context switches per second. This results in CPU cache thrashing—as user-space buffers evict hot instruction caches and working sets from L1/L2 caches—and introduces severe jitter.
Implementing splice() and vmsplice() in Custom Proxy Daemons
Linux provides the splice() system call (alongside vmsplice() and tee()) to move data between two file descriptors without ever copying data into user-space address space. splice() moves data to and from a pipe buffer (pipefs), which acts as an in-kernel ring buffer of memory pages.
+---------------------------------------------------------+
|                  Traditional I/O Path                   |
|                                                         |
|  [NIC] -> [Kernel Socket] ---> (Context Switch)         |
|                          ---> [User-Space Buffer]       |
|                          ---> (Context Switch)          |
|                          ---> [Kernel Socket] -> [NIC]  |
+---------------------------------------------------------+

+---------------------------------------------------------+
|                     Zero-Copy `splice()`                |
|                                                         |
|  [Inbound Socket] --\                                   |
|                      \                                  |
|                       +--> [In-Kernel Pipe Buffer]      |
|                      /                                  |
|  [Outbound Socket] -/                                   |
|  (Data never enters user-space; zero CPU cache thrash)  |
+---------------------------------------------------------+
How splice() Operates Under the Hood
The signature of splice() in C is:
loff_t splice(int fd_in, loff_t *off_in, int fd_out, loff_t *off_out, size_t len, unsigned int flags);
When building a high-throughput proxy daemon in Rust or Go, splice() can be wrapped via Foreign Function Interfaces (FFI) or direct system call wrappers (such as Rust’s nix crate or Go’s golang.org/x/sys/unix).
To bridge an incoming socket (client_fd) to an outgoing tunnel socket (tunnel_fd) using an intermediate pipe:
- Create an Anonymous Pipe: Establish a unidirectional pipe pair via
pipe2(O_NONBLOCK)during daemon initialization. - Splice Inbound to Pipe: Call
splice(client_fd, NULL, pipe_write_fd, NULL, len, SPLICE_F_MOVE | SPLICE_F_NONBLOCK). This instructs the kernel to point page references from the socket buffer directly into the pipe buffer ring without copying bytes. - Splice Pipe to Outbound: Call
splice(pipe_read_fd, NULL, tunnel_fd, NULL, len, SPLICE_F_MOVE | SPLICE_F_NONBLOCK). The kernel drains the pipe pages directly into the target socket buffer.
Architectural Gotchas & Edge Cases
- File Descriptor Constraints: At least one of the two file descriptors passed to
splice()must refer to a pipe. You cannot splice directly from socket A to socket B; you must route through an intermediate pipe pair. - Non-Blocking Semantics: Proxies must handle
EAGAINgracefully. If the pipe is full or the socket buffer cannot accept more data,splice()returns-1witherrno = EAGAIN, requiring integration with epoll/kqueue event loops. - TLS and Decryption:
splice()operates purely on raw byte streams. If your tunnel implements TLS termination at the proxy layer, standardsplice()cannot be applied to encrypted ciphertext unless you utilize kernel-level TLS (KTLS) offloading (setsockoptwithSOL_TCPandTCP_ULP). With KTLS enabled, the kernel handles TLS decryption inside kernel space, allowingsplice()to stream cleartext payloads directly into proxy routing pipes.
2. The SO_REUSEPORT Scaling Crisis: Distributing Incoming Tunnel Connections Across Multi-Core Go & Rust Daemons
The Thundering Herd Problem and Single-Socket Bottlenecks
Historically, high-performance network daemons relied on a single master listening socket (listenfd). When a new TCP connection arrived via the 3-way handshake, the kernel woke up worker threads or processes blocked on accept().
This design triggers the infamous thundering herd problem: all worker threads wake up simultaneously, contend for the mutex lock around the accept queue, and only one thread successfully accepts the connection while the rest go back to sleep. On a 128-core bare-metal server handling 100,000 new connections per second, this creates catastrophic CPU lock contention on the socket lock (sk_lock), skyrocketing latency.
Enter SO_REUSEPORT
To eliminate the single-listener bottleneck, Linux introduced the SO_REUSEPORT socket option (expanded significantly in Linux 3.9+). SO_REUSEPORT allows multiple independent sockets to bind to the exact same IP address and port combination.
When a connection arrives, the kernel’s TCP layer uses a hashing algorithm based on the 4-tuple (source IP, source port, destination IP, destination port) combined with a per-socket seed to route the incoming connection directly to a specific listener socket. Each worker thread or process maintains its own independent listener socket and accept queue, completely eliminating lock contention.
                         [Incoming TCP SYN Packet]
                                     |
                                     v
                       +---------------------------+
                       | Kernel 4-Tuple Hash Ring  |
                       +---------------------------+
                        /            |            \
                       /             |             \
                      v              v              v
               [Worker Thread 1] [Worker Thread 2] [Worker Thread 3]
               (SO_REUSEPORT)    (SO_REUSEPORT)    (SO_REUSEPORT)
Implementing SO_REUSEPORT in Go and Rust Daemons
The Go Implementation Challenge
Go’s runtime manages network polling via its internal netpoller (backed by epoll on Linux) and abstracts socket creation inside the net package. By default, standard net.Listen does not set SO_REUSEPORT.
To leverage SO_REUSEPORT in Go for multi-core proxy scaling, you must configure the socket using a syscall control callback before binding:
package main

import (
	"context"
	"fmt"
	"net"
	"syscall"
)

func createReusePortListener(network, address string, port int) (net.Listener, error) {
	lc := net.ListenConfig{
		Control: func(network, address string, c syscall.RawConn) error {
			var err error
			c.Control(func(fd uintptr) {
				// Set SO_REUSEADDR
				err = syscall.SetsockoptInt(int(fd), syscall.SOL_SOCKET, syscall.SO_REUSEADDR, 1)
				if err != nil {
					return
				}
				// Set SO_REUSEPORT
				err = syscall.SetsockoptInt(int(fd), syscall.SOL_SOCKET, syscall.SO_REUSEPORT, 1)
			})
			return err
		},
	}

	addr := fmt.Sprintf("%s:%d", address, port)
	return lc.Listen(context.Background(), network, addr)
}
The Rust Implementation
In Rust, using async runtimes like Tokio or Mio, you can construct custom socket primitives using standard library net or crates like socket2 to configure SO_REUSEPORT cleanly across multiple worker threads mapped to CPU cores:
use socket2::{Domain, Protocol, Socket, Type};
use std::net::SocketAddr;

fn create_reuse_listener(addr: SocketAddr) -> std::io::Result<std::net::TcpListener> {
    let domain = Domain::for_address(addr);
    let socket = Socket::new(domain, Type::STREAM, Some(Protocol::tcp()))?;

    // Enable SO_REUSEADDR and SO_REUSEPORT
    socket.set_reuse_address(true)?;
    socket.set_reuse_port(true)?;
    socket.set_nonblocking(true)?;

    socket.bind(&addr.into())?;
    socket.listen(1024)?;

    Ok(socket.into())
}
The SO_REUSEPORT Scaling Crisis: Connection Imbalance Under Webhook Bursts
While SO_REUSEPORT solves lock contention, it introduces a subtle scaling crisis under specific traffic distributions—such as high-frequency webhook traffic originating from a single cloud provider (e.g., GitHub, Stripe, or Slack webhooks).
Root Cause of the Imbalance
The kernel’s 4-tuple hashing function for SO_REUSEPORT uses a static hash key generated when the socket is created. Because webhook traffic from a single major provider often originates from a limited pool of source IPs interacting with a single destination proxy port, the entropy of the 4-tuple is heavily constrained.
Consequently, the kernel hash function can suffer from hash collisions or skew, routing 80% of incoming webhook connections to Worker Thread 1 while Workers 2 through 8 sit idle. This leads to thread starvation, queue backups, and sporadic timeouts.
Mitigation Strategies
- BPF Load Balancing (SO_ATTACH_REUSEPORT_CBPF / EBPF):
Instead of relying on the kernel’s default hash, advanced proxies attach a custom eBPF (Extended Berkeley Packet Filter) program to the listener sockets using
setsockoptwithSO_ATTACH_REUSEPORT_EBPF. The eBPF program inspects the inner payload, HTTP headers, or custom routing keys, and explicitly directs the socket selection index, ensuring perfect round-robin or load-aware distribution across worker threads. - Work-Stealing Accept Queues: In user-space daemon architectures (particularly in custom Rust async runtimes), worker threads share an overflow ring buffer. If a worker’s local accept rate exceeds its processing capacity, newly accepted file descriptors are pushed to a shared global work-stealing queue for idle worker threads to pull and process.
3. Fighting Buffer Bloat in Reverse Proxies: Fine-Tuning TCP Window Scaling for Local Development Tunnels
What is Buffer Bloat in Tunneling?
Local development tunnels (exposing a local port like http://localhost:3000 to the public internet via a secure edge proxy) introduce complex network topologies. Developers frequently test these tunnels over high-bandwidth, high-latency residential connections (e.g., 500 Mbps fiber with 30ms–80ms latency to regional edge nodes) or mobile hotspots.
Buffer bloat occurs when excess buffer capacity in the network path—whether inside router buffers, ISP queues, or the Linux kernel’s TCP socket receive/send buffers—fills up completely. Instead of dropping packets to signal congestion, intermediate buffers queue them up. For reverse proxies handling large file uploads or artifact deployments through a tunnel, bloated socket buffers cause latency to spike from 25ms to over 2,000ms (Bufferbloat Induced Latency), breaking interactive streams and triggering premature HTTP gateway timeouts.
Diagnosing Latency Spikes During Large File Uploads
When inspecting a proxy daemon under heavy upload load using tools like ss, bpftrace, or ethtool, you will often observe:
* Bloated Send/Receive Queues: The Send-Q and Recv-Q metrics in ss -t -i remain stubbornly high.
* Aggressive CUBIC Congestion Collapse: Default Linux TCP stacks traditionally utilized the CUBIC congestion control algorithm. CUBIC aggressively increases window size until packet loss occurs. On high-bandwidth, high-delay links (high Bandwidth-Delay Product or BDP), CUBIC overfills router buffers, causing massive queuing delays before detecting congestion.
The Math of BDP (Bandwidth-Delay Product)
The BDP determines how much data can be “in flight” at any given moment to fully saturate a network link:
$$\text{BDP (bits)} = \text{Bandwidth (bps)} \times \text{Round-Trip Time (seconds)}$$
For a 100 Mbps tunnel connection with an RTT of 50ms ($0.050$s):
$$\text{BDP} = 100,000,000 \times 0.050 = 5,000,000 \text{ bits} = 625,000 \text{ bytes} \approx 610 \text{ KB}$$
If the Linux kernel socket buffer (net.ipv4.tcp_wmem) is misconfigured to a static maximum of 16 MB, the TCP stack will pump 16 MB of data into the socket buffer faster than the residential client can acknowledge it. The local NIC and intermediary buffers bloat to absorb the surplus, ruining interactive latency.
Fine-Tuning BBR Congestion Control and Socket Buffers
1. Switching to BBR (Bottleneck Bandwidth and RTT)
Unlike CUBIC, which reacts to packet loss, Google’s BBR (Bottleneck Bandwidth and Round-trip propagation time) congestion control algorithm models the network bottleneck explicitly. It measures the maximum delivery rate and minimum RTT continuously, pacing packet transmission to match the actual path capacity rather than overfilling buffers.
To enable BBR on your Linux proxy server hosting the tunnel edge:
# Check available congestion control algorithms
sysctl net.ipv4.tcp_available_congestion_control

# Enable BBR immediately
sudo sysctl -w net.core.default_qdisc=fq
sudo sysctl -w net.ipv4.tcp_congestion_control=bbr

# Make permanent in /etc/sysctl.conf
echo "net.core.default_qdisc=fq" | sudo tee -a /etc/sysctl.conf
echo "net.ipv4.tcp_congestion_control=bbr" | sudo tee -a /etc/sysctl.conf
2. Dynamic Socket Buffer Tuning (tcp_rmem and tcp_wmem)
Instead of leaving socket buffer sizes to static defaults or over-allocating memory, configure dynamic socket buffer tuning in /etc/sysctl.conf to accommodate high BDP tunnels without inducing buffer bloat:
# Min, Default, and Max socket receive buffers (bytes)
net.ipv4.tcp_rmem = 4096 87380 16777216

# Min, Default, and Max socket send buffers (bytes)
net.ipv4.tcp_wmem = 4096 65536 16777216

# Enable TCP window scaling (RFC 1323)
net.ipv4.tcp_window_scaling = 1

# Enable MTU discovery to prevent fragmentation
net.ipv4.tcp_mtu_discovery = 1
3. Programmatic Socket Tuning in Go and Rust Proxy Daemons
In addition to system-wide sysctl adjustments, production proxy daemons should explicitly configure socket buffer sizes and congestion control algorithms on incoming and outgoing tunnel connections programmatically at runtime.
Rust Implementation (Setting Congestion Control and Buffer Sizes):
use socket2::{Socket, Domain, Type, Protocol};
use std::os::unix::io::AsRawFd;

fn tune_proxy_socket(socket: &Socket) -> std::io::Result<()> {
    // Set custom socket send and receive buffer sizes (e.g., 2MB)
    socket.set_send_buffer_size(2 * 1024 * 1024)?;
    socket.set_recv_buffer_size(2 * 1024 * 1024)?;

    // Set TCP congestion control to BBR via setsockopt (SOL_TCP, TCP_CONGESTION)
    let bbr = b"bbr\0";
    unsafe {
        let ret = libc::setsockopt(
            socket.as_raw_fd(),
            libc::IPPROTO_TCP,
            libc::TCP_CONGESTION,
            bbr.as_ptr() as *const libc::c_void,
            bbr.len() as libc::socklen_t,
        );
        if ret != 0 {
            return Err(std::io::Error::last_os_error());
        }
    }

    Ok(())
}
Go Implementation (Setting Socket Options):
import (
	"net"
	"syscall"
)

func configureSocketBuffers(c net.Conn) error {
	tcpConn, ok := c.(*net.TCPConn)
	if !ok {
		return nil
	}

	rawConn, err := tcpConn.SyscallConn()
	if err != nil {
		return err
	}

	var sockErr error
	err = rawConn.Control(func(fd uintptr) {
		// Set socket send buffer to 2MB
		sockErr = syscall.SetsockoptInt(int(fd), syscall.SOL_SOCKET, syscall.SO_SNDBUF, 2*1024*1024)
		if sockErr != nil {
			return
		}
		// Set socket receive buffer to 2MB
		sockErr = syscall.SetsockoptInt(int(fd), syscall.SOL_SOCKET, syscall.SO_RCVBUF, 2*1024*1024)
		if sockErr != nil {
			return
		}
		// Set TCP congestion control to BBR
		sockErr = syscall.SetsockoptString(int(fd), syscall.IPPROTO_TCP, syscall.TCP_CONGESTION, "bbr")
	})

	if err != nil {
		return err
	}
	return sockErr
}
Summary and Architectural Checklist
Building high-throughput, low-latency tunneling proxies demands moving past naive application-layer abstractions and mastering the Linux kernel networking subsystem. By integrating the techniques outlined in this guide, engineering teams can eliminate major performance bottlenecks:
- Eliminate CPU Cache Thrashing: Adopt zero-copy ingress routing with
splice()andvmsplice()paired with pipe buffers and KTLS to keep large payloads entirely within kernel space. - Scale Multi-Core Daemons Safely: Utilize
SO_REUSEPORTcombined with custom eBPF packet filters to distribute incoming webhook and tunnel connections evenly across worker threads without thundering herd lock contention. - Eradicate Buffer Bloat: Shift away from legacy CUBIC congestion control, enable BBR, configure Fair Queueing (
fq), and dynamically tune socket send/receive buffers to match real-world Bandwidth-Delay Products.
Implementing these low-level optimizations ensures your proxy daemons can sustain millions of requests, gigabits of throughput, and sub-millisecond tail latencies even under extreme network volatility.
Related InstaTunnel pages
Continue from this article into the most relevant product guides and workflows.
Related Topics
Keep building with InstaTunnel
Read the docs for implementation details or compare plans before you ship.